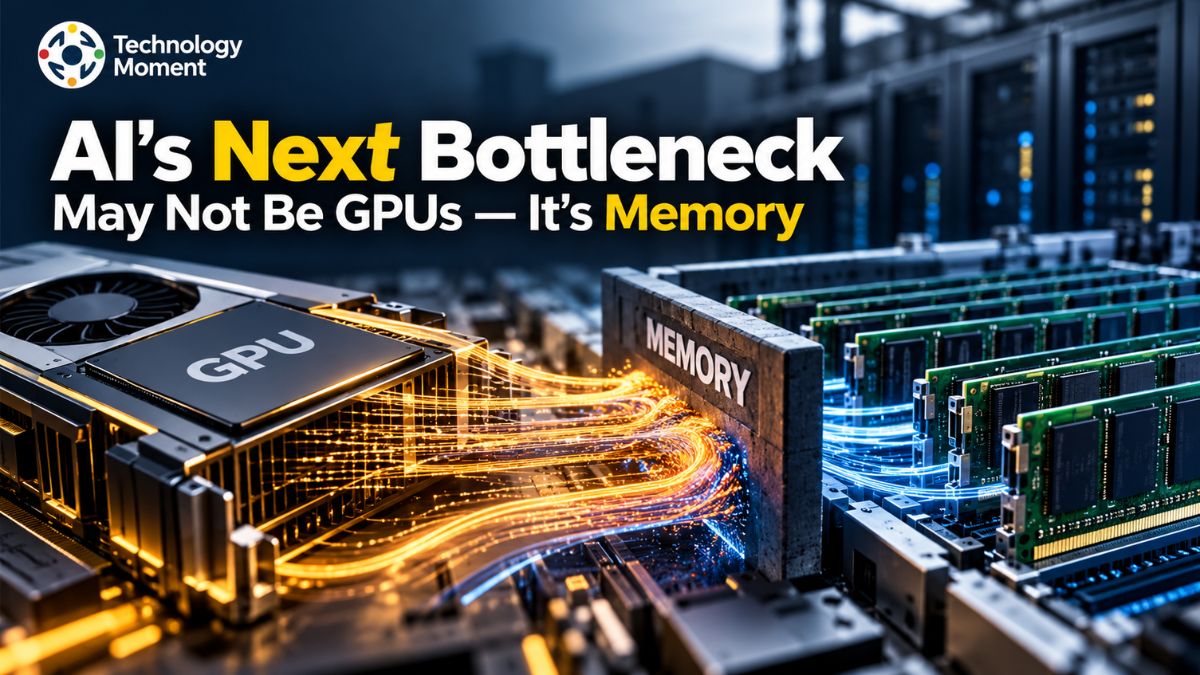
For years, the race to build more capable AI systems has centered on faster GPUs, larger AI accelerators, and greater computing power. But as models become larger, context windows expand, and AI inference happens at massive scale, another part of the infrastructure is receiving much more attention: memory. Recent technical research and industry analysis point to memory bandwidth, capacity, and data movement as increasingly important constraints for modern AI inference.
This changes the way we should think about AI performance. A powerful GPU can perform an enormous number of calculations, but it still needs to receive the right data at the right speed. If memory cannot keep up, additional compute does not necessarily translate into proportional real-world performance. This is why technologies such as High-Bandwidth Memory (HBM) are becoming central to AI infrastructure, while KV cache, long-context workloads, and growing inference demand are creating new memory challenges.
At Technology Moment, we look beyond the headline hardware specifications to understand what is actually changing underneath the technology industry. In this article, we explore why AI’s next bottleneck may not simply be GPU compute, how memory bandwidth and capacity affect AI workloads, why HBM matters, and what the growing memory challenge could mean for the future of AI infrastructure. The bigger question is no longer just how much AI can compute, but how efficiently it can move and access the data required to compute.
Why AI Is Moving Beyond the GPU Bottleneck
For years, the AI hardware race has largely been defined by GPUs. More GPU compute has meant more processing power for training large language models, generative AI systems, recommendation engines, and other demanding workloads. However, the rapid growth of AI is exposing another challenge: the ability to move and store data quickly enough for those powerful processors. This is where the idea of an AI memory bottleneck becomes increasingly important. A modern AI GPU can perform an enormous amount of computation, but its performance also depends on how quickly model weights, activations, and other data can reach the computing cores.
If memory bandwidth cannot keep pace with GPU compute, adding more processing power may not deliver a proportional improvement in real-world performance. Research on LLM inference increasingly describes this shift from a primarily compute-focused problem toward memory and I/O constraints. The change is particularly visible when comparing AI training with AI inference. Training large models can make heavy use of GPU compute because many tokens are processed together, creating highly parallel workloads. Inference is different. During the decode stage, an AI system generates output one token at a time and repeatedly accesses model weights and the growing KV cache.
This can make the workload strongly dependent on memory bandwidth and data movement. As AI applications move toward longer context windows, AI agents, real-time assistants, and larger numbers of simultaneous users, memory becomes an increasingly important part of the overall AI infrastructure equation. The question is therefore no longer simply how powerful an AI GPU is. It is also how efficiently the entire system can feed that GPU with data.
What Is the AI Memory Bottleneck?
The AI memory bottleneck occurs when the memory system cannot supply data to AI processors quickly enough or cannot hold all the data required by the workload. Two concepts are particularly important here: memory bandwidth and memory capacity. Memory bandwidth describes how quickly data can be transferred between memory and the processor, while memory capacity determines how much data can be stored. Both can limit AI performance, but they create different problems.
A model may technically fit inside available GPU memory but still run inefficiently because the system cannot move the required data quickly enough. Conversely, a workload may require more memory capacity than a single accelerator provides, forcing data to be distributed across multiple GPUs or other parts of the memory hierarchy.
This is closely connected to the concept of the memory wall in AI computing. As AI processors become increasingly capable, the gap between compute performance and memory movement can become more important. During LLM inference, particularly decode, the processor may have plenty of theoretical compute capability while spending significant time waiting for data. Recent research describes autoregressive decode as deeply memory-bandwidth-bound because model weights and the KV cache must be accessed as tokens are generated.
The problem becomes more complicated as AI workloads grow. Larger models contain more model weights, longer context windows increase the amount of information that must remain available, and higher concurrency means multiple requests compete for memory resources. This means an AI hardware bottleneck cannot always be solved simply by purchasing faster GPUs. Memory bandwidth, memory capacity, latency, data movement, interconnects, and software optimization all contribute to the final performance of an AI system. The emerging AI memory bottleneck is therefore a system-level challenge rather than a problem with one component alone.
Why AI Needs So Much Memory
The growing memory requirements of AI are closely connected to the increasing complexity of modern models and the way they are deployed. Large language models need memory to store model weights, intermediate data, and other information required during computation. As models become larger, their parameter data can require substantial amounts of GPU memory. But model size is only one part of the equation. AI inference can also create significant memory pressure through longer context windows and larger numbers of simultaneous requests. When an AI system serves many users at once, each request can require its own working state, increasing overall memory capacity requirements.
One of the most important factors is the KV cache. During autoregressive LLM inference, the system stores key and value information from previous tokens so that it can be reused while generating subsequent tokens. As the context becomes longer, the KV cache grows. Higher concurrency can increase the total cache requirement even further. Research and industry analysis increasingly identify this cache as an important source of memory capacity and bandwidth pressure in long-context inference.
This creates an interesting relationship between memory capacity and memory bandwidth. More capacity allows an AI system to keep larger models, longer contexts, and more concurrent workloads in memory. More bandwidth allows that information to move quickly enough to keep the processors productive. Neither factor alone is sufficient for every workload. An AI data center serving short requests at high volume may have different requirements from a system running long-context reasoning or AI agents.
The result is a rapidly expanding demand for AI memory. Data centers need memory technologies that can support large AI workloads without creating excessive latency, power consumption, or communication overhead. As AI inference becomes a larger share of total infrastructure demand, memory is moving from being a supporting component to becoming a central design consideration.
HBM: The Memory Technology Powering Modern AI
High-Bandwidth Memory, commonly known as HBM, has become one of the most important memory technologies for modern AI accelerators. Unlike conventional memory architectures, HBM uses vertically stacked memory dies and a wide interface to provide very high data-transfer bandwidth close to the processor. This architecture is particularly valuable for AI workloads because GPUs and AI accelerators need to move enormous amounts of data while performing large numbers of calculations. HBM therefore addresses one of the central challenges in AI hardware: feeding powerful compute engines with data fast enough to keep them productive.
The importance of HBM becomes clearer when looking at AI inference. During memory-intensive workloads, the limiting factor may be how quickly model weights and cached information can be delivered to the compute cores rather than the theoretical number of calculations the accelerator can perform. Higher memory bandwidth can therefore improve the ability of an AI system to sustain data-intensive workloads. Research on LLM inference highlights this relationship between GPU compute growth and memory-bandwidth requirements.
The industry is also moving from HBM3E toward HBM4, reflecting the growing demand for both bandwidth and capacity. At the same time, the rapid expansion of AI infrastructure is increasing demand for HBM production. Recent industry reporting shows how strongly AI data-center demand is influencing the memory-chip market, with Samsung expecting HBM to represent nearly 30% of industry DRAM wafer capacity in 2027. Micron has also reported exceptionally strong demand for AI-related memory and significant long-term supply commitments.
However, HBM is not a complete solution to every AI memory challenge. Longer context windows, growing KV caches, higher concurrency, and increasingly demanding inference workloads continue to place pressure on memory capacity and bandwidth. This is why the future of AI hardware may involve a broader memory hierarchy that combines HBM with technologies such as SRAM, CXL memory, high-bandwidth flash, and other approaches designed to reduce data-movement costs.
The Hidden Problem: AI Inference Is Memory-Hungry
The rapid expansion of generative AI is changing where the hardest performance problems occur. During AI training, enormous amounts of computation can make GPU compute a major constraint. But once a model is deployed, the situation can look different. In many large language model workloads, especially during the decode stage, the system repeatedly reads model weights and previously generated context from memory while producing output one token at a time. That makes AI inference increasingly sensitive to memory bandwidth and data movement rather than raw GPU computing power.
Qualcomm’s 2026 analysis describes decode as predominantly memory-bound, while a recent academic survey similarly identifies memory and I/O as major constraints for large-scale LLM inference. This creates an important AI inference memory bottleneck. A powerful AI GPU may have enormous theoretical compute capability, but that capability is not always fully utilized if the processor has to wait for data to arrive. Memory bandwidth determines how quickly information can be supplied, while memory capacity determines how much information can remain available locally. Both matter when AI servers handle large models, long context windows, high concurrency, and increasingly complex AI workloads.
The issue becomes even more significant as businesses deploy AI assistants, agents, search systems, coding tools, and real-time applications at scale. More users mean more inference requests, while longer interactions increase the amount of information that must be retained. As a result, GPU memory, memory bandwidth, and AI infrastructure are becoming closely connected. The next phase of AI hardware optimization may therefore focus not only on faster processors, but also on reducing the time, energy, and cost required to move data.
KV Cache Could Become AI’s Next Memory Challenge
One of the less visible but increasingly important components of modern LLM inference is the KV cache. During generation, a large language model creates key and value information for tokens that have already been processed. Instead of calculating that information again for every new token, the system stores it in the KV cache and reuses it. This improves computational efficiency, but it introduces another challenge: the cache grows as the context becomes longer. During decode, the system repeatedly needs to read this accumulated information while generating the next token.
This makes KV cache particularly important for applications built around long context windows, extended conversations, document analysis, coding sessions, and AI agents. As more tokens remain active, the cache can consume substantial GPU memory. When many users are served simultaneously, each request can require its own cache, increasing the total memory requirement. A recent survey notes that KV-cache I/O can become a major part of decode workloads, while IEEE research describes KV cache as a growing bottleneck in both memory capacity and bandwidth as context lengths increase.
The challenge is not simply about having enough storage. The system must also access the cached information quickly enough to maintain acceptable inference performance. Moving the KV cache to slower memory can provide additional capacity but may introduce bandwidth and latency penalties. This is why researchers and hardware companies are exploring broader memory hierarchies, including HBM, SRAM, CXL memory, high-bandwidth flash, and other approaches.
For AI infrastructure, this represents a significant shift. Model weights were once the obvious memory concern, but the growing KV cache means the runtime state of an AI application can become just as important. As AI agents perform longer, more iterative tasks, efficient KV-cache management could become a central part of designing scalable LLM inference systems.
GPU Memory Bottleneck vs GPU Compute Bottleneck
The difference between a GPU compute bottleneck and a GPU memory bottleneck is important because the solution to each problem is different. A compute-bound workload needs more processing capability, while a memory-bound workload may benefit more from higher bandwidth, greater capacity, better caching, or improved data movement. Modern AI systems can experience both, depending on the workload and the stage of processing.
| GPU Compute Bottleneck | GPU Memory Bottleneck |
|---|---|
| Limited by available computing power | Limited by memory bandwidth or capacity |
| More GPU compute can improve performance | Faster memory access can improve performance |
| Common in highly parallel calculations | Common in memory-intensive inference |
| Focuses heavily on compute throughput | Focuses on bandwidth, capacity and data movement |
| Processor utilization can be high | Compute units may wait for data |
| More FLOPS can be valuable | More FLOPS may not solve the underlying problem |
| Often associated with compute-bound workloads | Often associated with memory-bound workloads |
For AI inference, this distinction becomes particularly relevant during token generation. Qualcomm describes the decode phase as overwhelmingly memory-bound because the system repeatedly reads model parameters and accumulated context while performing comparatively less arithmetic per token. A recent Springer survey similarly argues that large-scale LLM deployment has shifted important bottlenecks toward memory and I/O during inference.
This does not mean GPUs are becoming irrelevant. GPUs remain fundamental to modern AI chips, AI accelerators, AI servers, and data centers. The more accurate conclusion is that GPU performance cannot be considered separately from the memory system surrounding it. An accelerator with impressive theoretical compute may still deliver limited real-world performance when memory bandwidth, capacity, latency, or interconnect performance becomes the limiting factor.
That is why the future of AI hardware is increasingly being evaluated through a broader lens: compute performance, memory bandwidth, memory capacity, data movement, power efficiency, and cost all need to work together.
The AI Memory Supply Chain Is Becoming Strategic
The memory challenge is no longer limited to the architecture of an individual AI server. It is increasingly affecting the broader semiconductor supply chain. High-Bandwidth Memory, or HBM, has become an important component of modern AI accelerators because it provides very high bandwidth close to the compute processor. As AI data centers deploy more accelerators and inference workloads expand, demand for HBM and other advanced memory technologies is increasing. Recent reporting from Micron shows how strongly AI demand is affecting the memory market, with the company reporting orders exceeding available capacity and expecting tighter supply-demand conditions in the coming years.
The HBM market also creates a connection between AI memory demand and conventional DRAM supply. Samsung recently said HBM could account for nearly 30% of industry DRAM wafer capacity in 2027, compared with around 20% currently. Because HBM and conventional DRAM use overlapping manufacturing capacity, expanding HBM production can influence the availability of standard memory as well.
This makes HBM supply, HBM demand, memory chips, and advanced packaging strategically important to AI infrastructure. HBM is not simply another component that can be added whenever demand increases; manufacturing involves specialized processes and advanced packaging capacity. Industry investment is therefore expanding around AI-related memory production, with SEMI reporting significant growth in memory-sector fab-equipment investment driven by demand for HBM, DDR5, and other advanced memory technologies.
The supply-chain implications extend beyond HBM. As AI inference creates larger KV caches and more memory-intensive workloads, the industry is exploring additional layers of the memory hierarchy, including SRAM, CXL-based memory, high-bandwidth flash, and storage systems designed specifically for AI workloads. The result is a broader shift in AI infrastructure economics: access to sufficient memory capacity, bandwidth, manufacturing capacity, and advanced packaging may become just as important to scaling AI systems as access to cutting-edge GPUs.
Beyond HBM: What Comes Next?
HBM has become a foundational technology for modern AI accelerators because it provides the high memory bandwidth required by demanding AI workloads. But HBM alone may not be enough as AI inference moves toward longer context windows, higher concurrency, and increasingly complex AI agents. The central challenge is no longer simply providing more bandwidth; AI systems also need substantially more memory capacity without sacrificing access speed, efficiency, or cost. Recent industry analysis describes this as a shift toward a more diversified AI memory hierarchy, with technologies such as SRAM, CXL memory, High-Bandwidth Flash (HBF), and storage-based tiers being explored alongside HBM.
One important direction is CXL memory. Compute Express Link can provide an additional memory tier between high-speed accelerator memory and conventional system memory, making it useful for workloads where HBM capacity is insufficient. Research into CXL memory pooling specifically identifies long-context LLM inference and KV cache growth as use cases where additional pooled memory can help extend the usable memory capacity of AI servers.
Another emerging approach is High-Bandwidth Flash, or HBF. Unlike conventional flash storage, HBF is being explored as a higher-capacity memory tier that could help accommodate large KV caches. Research published in 2026 suggests that KV-cache access patterns can make high-bandwidth flash particularly interesting for long-context inference.
There is also growing interest in SRAM, processing-in-memory, compute near memory, and disaggregated memory architectures. The goal behind these approaches is similar: reduce unnecessary data movement and keep frequently accessed information closer to computation. The likely direction, therefore, is not an HBM replacement appearing overnight. Instead, AI infrastructure may evolve toward a multi-level memory hierarchy, where HBM handles the most bandwidth-sensitive data while CXL, HBF, SRAM, DRAM, and storage serve different capacity, latency, and cost requirements.
Can Software Reduce the AI Memory Bottleneck?
Hardware is only one part of the solution to the AI memory bottleneck. Software can significantly reduce how much memory an AI workload requires and how often data needs to move between different memory levels. This is particularly important for AI inference, where model weights, activations, and KV cache can create substantial memory and bandwidth pressure. Current research identifies techniques such as quantization, KV-cache compression, FlashAttention, PagedAttention, speculative decoding, offloading, prefix caching, and continuous batching as important approaches for improving LLM inference efficiency.
Quantization is one of the most widely discussed techniques. By representing model parameters or cache data with fewer bits, systems can reduce memory capacity requirements and potentially move more information through a given memory bandwidth. This can make larger models easier to deploy within available GPU memory. Similarly, KV-cache compression can reduce the amount of data that must remain available during long-context inference. Industry research in 2026 has highlighted both KV-cache compression and expanded memory capacity through CXL as complementary approaches to the growing memory challenge.
Software can also improve the way data is accessed. Techniques such as asynchronous KV-cache prefetching attempt to move required information into faster cache levels before it is needed, helping overlap memory access with computation. A 2026 AAAI paper reported improvements from such a prefetching approach, illustrating how software-level scheduling can help address HBM bandwidth limitations.
However, software optimization has limits. If models become larger, context windows continue expanding, and AI applications serve more simultaneous users, the underlying demand for memory capacity, memory bandwidth, and data movement can continue growing. Software can make the existing hardware more efficient, but it cannot eliminate physical memory requirements altogether.
The more realistic future is therefore a combination of software optimization and hardware innovation. Better algorithms, quantization, cache management, and scheduling can reduce memory pressure, while HBM, CXL memory, HBF, SRAM, and new AI processors can provide additional capacity and bandwidth where software alone cannot.
Is Memory Really the Next Bottleneck for AI?
The answer depends heavily on the workload. It would be too broad to say that memory has completely replaced GPU compute as the main limitation across all AI applications. Training, inference, scientific workloads, multimodal systems, and AI agents can have very different performance characteristics. However, there is strong evidence that memory bandwidth, memory capacity, and data movement are becoming increasingly important constraints for large-scale LLM inference. A 2026 survey in Artificial Intelligence Review describes a shift from compute limitations during training toward memory and I/O limitations during inference, particularly as model sizes and context windows grow.
Training involves enormous amounts of parallel computation, whereas autoregressive inference repeatedly generates tokens and accesses model weights and KV cache. During this process, the workload can become strongly memory-bound. Qualcomm’s analysis similarly argues that modern AI inference performance is increasingly determined by how effectively the system moves data rather than simply by how much compute it provides.
This does not mean the GPU era is ending. GPUs and AI accelerators will remain central to AI infrastructure. Instead, the definition of performance is becoming broader. A system needs sufficient GPU compute, but it also needs enough memory capacity, memory bandwidth, low-latency interconnects, efficient data movement, and optimized software to use that compute effectively.
The growing importance of KV cache makes this particularly visible. Long-context LLMs can generate memory requirements that exceed the capacity of on-package HBM, encouraging research into CXL memory, HBF, memory pooling, and other approaches. So, rather than asking whether memory or GPUs will dominate AI, it is more useful to view them as parts of one system. The next generation of AI infrastructure will likely be designed around the relationship between compute and memory. In that sense, the emerging AI memory bottleneck is less about replacing GPUs and more about making sure increasingly powerful processors can actually access the data they need.
Frequently Asked Questions
Is memory the next bottleneck for AI?
Memory is becoming an increasingly important bottleneck for many AI inference workloads, but it is not the only one. GPU compute, networking, storage, interconnects, power, and software can also limit performance. The specific bottleneck depends on the workload. For long-context LLM inference, however, memory bandwidth and KV-cache capacity are increasingly significant concerns.
Why does AI need so much memory?
AI systems need memory to store model weights and intermediate information required during computation. LLM inference also creates a growing KV cache containing information from previously processed tokens. Larger models, longer context windows, and more simultaneous users can therefore increase total memory requirements substantially.
Why is HBM important for AI?
High-Bandwidth Memory (HBM) provides very high data-transfer bandwidth close to AI processors. This helps GPUs and AI accelerators access large volumes of model data efficiently. HBM is particularly valuable for memory-intensive AI workloads where conventional memory bandwidth may limit performance. However, its capacity constraints mean additional memory tiers may be needed for future inference workloads.
How does memory bandwidth affect AI performance?
Memory bandwidth determines how quickly data can move between memory and an AI processor. If an AI workload requires more data movement than the memory system can provide, compute resources may remain underutilized. This is particularly relevant to memory-bound LLM inference, where model weights and KV-cache data must be accessed repeatedly during token generation.
What is the AI memory bottleneck?
The AI memory bottleneck occurs when available memory capacity, bandwidth, or data-access performance prevents an AI workload from using its compute resources efficiently. It can appear when a model or KV cache does not fit in available GPU memory, or when the system cannot move required data quickly enough.
What is the memory wall in AI?
The memory wall describes the growing gap between computing capability and the speed at which data can be supplied to the processor. As AI accelerators become faster, memory and data movement can increasingly determine actual system performance. This is one reason modern AI architecture is placing greater emphasis on memory hierarchy and bandwidth.
Why are GPUs not enough for AI?
GPUs remain essential to AI, but GPU compute alone does not determine performance. AI workloads also depend on memory capacity, memory bandwidth, interconnects, and software. A highly capable GPU can still encounter a memory bottleneck if the required model data or KV cache cannot be accessed quickly enough.
How much memory do AI models need?
There is no single memory requirement for every AI model. It depends on model size, numerical precision, context length, batch size, KV-cache size, and workload type. A model’s weights may fit into available GPU memory while its inference workload still requires additional memory for activations and KV cache.
How does HBM improve AI performance?
HBM provides high memory bandwidth through a wide interface and close integration with the compute package. This allows AI processors to access large amounts of data quickly, which can improve performance for bandwidth-sensitive workloads. HBM therefore plays a major role in modern AI accelerators and data centers.
Why is AI inference memory intensive?
AI inference can become memory intensive because the system repeatedly accesses model weights and maintains information such as the KV cache. During autoregressive decoding, tokens are generated sequentially, creating repeated memory-access operations. As context length and concurrency increase, memory requirements can rise significantly.
What causes memory bottlenecks in LLM inference?
Major causes include large model weights, limited HBM capacity, high memory-bandwidth requirements, growing KV caches, long context windows, and high request concurrency. These factors can increase both the amount of data that must be stored and the speed at which that data needs to be accessed.
How does KV cache affect AI memory?
KV cache stores information from previously processed tokens so an LLM can reuse it during generation. Its size generally grows with context length and workload conditions, increasing GPU memory capacity requirements. When the cache becomes too large for available HBM, systems may need compression, recomputation, offloading, or additional memory tiers.
Is AI limited by memory bandwidth?
Some AI workloads are strongly limited by memory bandwidth, while others remain primarily compute-bound. LLM decode is a notable example of a workload where memory bandwidth can become a major constraint because model weights and KV-cache information must be repeatedly accessed during token generation.
Why is AI memory demand increasing?
AI memory demand is increasing because models are becoming larger, context windows are expanding, inference workloads are scaling, and AI applications are serving more concurrent users. The growth of AI agents and long-context applications also increases the amount of information that systems may need to keep accessible during inference.